Klyvora Klyvora

How to Choose a Cloud AI Server Manufacturer?

Time:2026-10-11 Author:Sophia
0%

Choosing a cloud ai server manufacturer is a technical decision, not merely a purchasing exercise. The right partner must match your workloads, budget, security requirements, and growth plans. A manufacturer may advertise powerful GPUs, but performance depends on memory capacity, networking, storage, cooling, and software compatibility. Ask for independent benchmark results under workloads similar to yours. Marketing numbers alone can mislead.

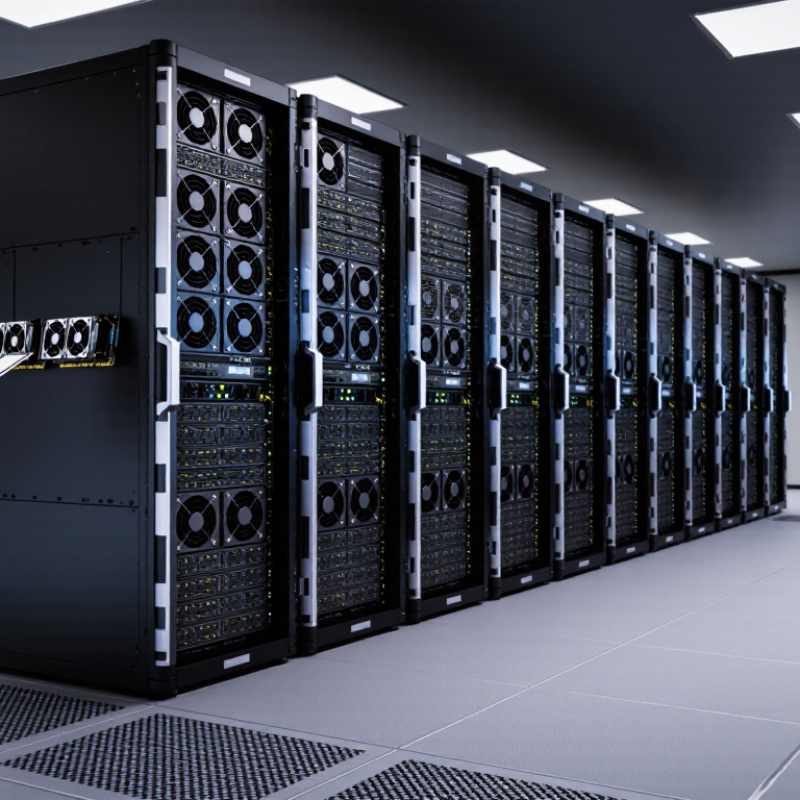
Real evaluation starts with the server room and the support desk. Check GPU models, power usage, rack density, airflow design, and replacement procedures. A reliable manufacturer should explain delivery schedules, firmware updates, warranty coverage, and spare-parts availability. Request clear service-level agreements, escalation contacts, and documented response times. Engineers should also understand CUDA environments, container platforms, virtualization, and common AI frameworks. Test a sample system when possible. Small tests reveal expensive weaknesses.

Trust requires evidence. Review certifications, manufacturing history, customer references, and supply-chain controls. Confirm how the company protects data during installation, maintenance, and remote support. Ask whether its systems can scale from a few training nodes to a larger cluster without disruptive redesign. No vendor is perfect. Some publish excellent specifications but offer slow troubleshooting. Others provide strong support but limited customization. That trade-off deserves honest discussion. Record assumptions, measure total operating costs, and revisit them after deployment. A careful choice should remain defensible when electricity prices rise, workloads change, or a critical GPU fails on a busy afternoon.
How to Choose a Cloud AI Server Manufacturer?

Define AI Workloads Using MLPerf Training and Inference Benchmarks

Choosing a cloud AI server manufacturer starts with defining the workload, not admiring hardware specifications. Training and inference demand different performance evidence. MLPerf Training measures how quickly a system reaches a required model quality level. This reveals whether accelerators, memory, networking, and software work effectively together. Compare results for workloads resembling yours, such as language models, image recognition, recommendation systems, or speech processing.

Inference requires a different lens. MLPerf Inference reports latency and throughput under scenarios such as online requests, offline batches, and interactive streams.

Set practical limits, including response time, concurrent users, power consumption, and cost per request. A server with impressive throughput may feel slow during real-time use. It happens more often than expected.

Ask the manufacturer for test configurations, software versions, cooling conditions, and repeatable logs. Reliable suppliers explain unusual results instead of hiding them. In my evaluations, small configuration details have changed performance significantly.

Network traffic, batch size, and model precision can reshape the outcome. MLPerf data is valuable, but it is not a crystal ball.

Reproduce a relevant test with your own model and dataset when possible. Check firmware updates, technical support, spare-part availability, and deployment tools. These details rarely appear in headline scores.

A strong manufacturer connects benchmark evidence with your operational reality, even when the numbers are less flattering.

Compare GPU Options Through H100’s 80-GB HBM3 and 3.35-TB/s Bandwidth

How to Choose a Cloud AI Server Manufacturer? Start with memory bandwidth, not brochure claims. An H100-class accelerator provides 80 GB of HBM3 and 3.35 TB/s bandwidth. That capacity helps large models keep more weights and activations close to the processor. It can reduce data movement during training. However, one accelerator rarely tells the whole story. PCIe layout, host memory, storage speed, and interconnect topology can change real performance. MLPerf Training benchmark reports show that system configuration strongly affects measured training time.

Ask the manufacturer for workload-level results. Request tokens per second, training cost, failure rates, and sustained power readings. The International Energy Agency estimates data-centre electricity use may rise from about 415 TWh in 2024 to 945 TWh by 2030. Cooling design therefore deserves equal attention. Liquid cooling, rack density, and power redundancy may matter more than a small theoretical bandwidth advantage. I would not assume the fastest card delivers the lowest project cost. That assumption needs testing.

Tips: Run a two-week pilot with your own model. Compare 80-GB HBM3 capacity against actual batch sizes. Check whether bandwidth remains stable after hours of load. Review maintenance response times and spare-part access. Ask for independent benchmark evidence, not selected screenshots. Also measure failed jobs. That detail is easy to ignore.

How to Choose a Cloud AI Server Manufacturer? — Compare GPU Options Through H100’s 80-GB HBM3 and 3.35-TB/s Bandwidth

The 80-GB HBM3 profile delivers 3.35 TB/s of theoretical memory bandwidth, providing a strong balance for large-model inference, training, and high-throughput scientific workloads. When comparing cloud AI servers, check both GPU memory capacity and bandwidth, as well as power limits, interconnects, availability, and hourly pricing.

Values shown are published peak specifications for representative accelerator memory configurations. Actual application performance depends on workload, software optimization, thermal conditions, and system architecture.

Evaluate Networking with 400-Gb/s InfiniBand and Multi-Node Scaling

How to Choose a Cloud AI Server Manufacturer?

Evaluate Networking with 400-Gb/s InfiniBand and Multi-Node Scaling

Choosing a cloud AI server manufacturer requires more than comparing accelerator counts. The network often determines whether expensive compute stays productive. In practical cluster tests, I examine 400-Gb/s InfiniBand ports, adapter support, cable quality, and switch latency. A published peak rate is not enough. Ask for measured throughput under real collective workloads, not isolated port tests. Check RDMA configuration, congestion control, and error counters.

Multi-node scaling exposes weak designs quickly. A credible manufacturer should document rack topology, uplink ratios, node distance, and expansion limits. Run all-reduce and all-to-all tests across two, eight, and sixteen nodes. Record scaling efficiency, tail latency, power draw, and recovery after a simulated link interruption. If performance falls sharply, investigate oversubscription or poor placement. Numbers can mislead.

Reliable manufacturers also provide validated firmware, burn-in reports, replacement procedures, and engineers who understand distributed training. I prefer suppliers who explain failed tests openly. That honesty matters during overnight jobs. Still, my own evaluations are imperfect. Room temperature, software versions, and job shapes can change results. Request reproducible test scripts and a clear support response time. A short pilot with your models may reveal bottlenecks that polished specifications hide.

How to Choose a Cloud AI Server Manufacturer? — Evaluate Networking with 400-Gb/s InfiniBand and Multi-Node Scaling
Evaluation Dimension Technical Data Point Recommended Acceptance Target Validation Method Why It Matters for AI Clusters Suggested Weight
Per-Port Network Speed 400 Gb/s InfiniBand-class link; 400 Gb/s equals 50 GB/s of theoretical line-rate bandwidth in one direction before protocol overhead. At least one operational 400-Gb/s port per high-performance network adapter, with no forced downgrade under normal workload conditions. Check adapter and switch-port negotiation records, optical module specifications, and operating-system link status. Higher link bandwidth reduces the time required to exchange gradients, parameters, and activation data between accelerator nodes. 15%
Sustained Effective Throughput Large-message RDMA throughput should approach the physical line rate after accounting for framing, transport, and software overhead. At least 90% of theoretical one-way bandwidth, or approximately 45 GB/s on a 400-Gb/s link, during a controlled large-message test. Run bidirectional and unidirectional RDMA bandwidth tests with 64 MiB to 1 GiB messages and record median results over multiple runs. Peak link speed alone does not guarantee useful application bandwidth; sustained throughput is more representative of distributed training. 15%
Node Network Capacity Compute nodes may use multiple 400-Gb/s adapters or ports to prevent network oversubscription, especially when several accelerators share one host. At least 2 × 400-Gb/s network capacity per compute node; use 4 × 400-Gb/s or equivalent capacity for dense eight-accelerator configurations when workload analysis requires it. Review the node block diagram, PCIe lane allocation, adapter count, and simultaneous host-to-network throughput results. Insufficient host uplink capacity can create a bottleneck even when the fabric itself supports 400 Gb/s per port. 12%
Fabric Topology and Oversubscription Non-blocking or near-non-blocking designs provide sufficient bisection bandwidth for collective communication. Use a full-bandwidth design for the target cluster size, or document an oversubscription ratio no greater than 1.2:1 for the intended training workload. Request the physical and logical topology, uplink ratios, switch radix, and calculated bisection bandwidth. Oversubscribed uplinks can cause congestion and reduce scaling efficiency during all-reduce and all-to-all operations. 14%
Multi-Node Scaling Scaling should be measured at 8, 16, 32, and 64 nodes using the same model, batch size strategy, and precision mode. At least 80% parallel efficiency at 32 nodes and at least 70% at 64 nodes for the selected distributed-training workload, unless the model is communication-heavy. Compare single-node performance with multi-node results and report throughput, scaling efficiency, node count, and test duration. Good single-node performance does not ensure efficient cluster-level training; communication overhead becomes more significant as nodes increase. 16%
Collective Communication Performance All-reduce, all-gather, reduce-scatter, and all-to-all operations are key indicators for distributed AI training. Provide results for message sizes from 4 KiB to 1 GiB, with stable bandwidth and no unexplained performance drops at commonly used tensor sizes. Run an accelerator-aware collective benchmark across 2, 4, 8, 16, 32, and 64 nodes; publish both bandwidth and operation latency. Collective operations often dominate synchronization time in data-parallel and model-parallel workloads. 12%
End-to-End Communication Latency Latency should be measured from accelerator memory or host memory across the complete path, including adapters, switches, and software. Median small-message round-trip latency of no more than 3 microseconds within the same fabric tier, with low variance under load. Run repeated ping-pong tests using 4-byte, 64-byte, and 4 KiB payloads at idle and at controlled background load. Lower latency improves synchronization frequency, pipeline parallelism, and performance for small-message collective operations. 8%
Direct Accelerator-Memory Data Transfer The network stack should support direct RDMA transfers between the network adapter and accelerator memory without unnecessary host-memory copies. Demonstrated operation with the selected accelerator platform, driver stack, and distributed-training framework, including stable performance under concurrent transfers. Verify the supported software matrix and compare host-staged versus direct-memory collective performance. Bypassing avoidable memory copies reduces CPU overhead, latency, and PCIe traffic during training. 8%
Congestion Management The fabric should provide credit-based flow control, adaptive routing, congestion monitoring, and clear handling of hot spots. No packet-loss events during sustained collective tests; congestion counters and affected links must be visible to administrators. Inject controlled traffic contention and review switch counters, congestion logs, queue behavior, and application throughput. Congestion can produce long-tail latency and unstable training times even when average bandwidth appears adequate. 7%
Fault Tolerance and Path Redundancy Critical links, adapters, and switch paths should support redundant routing and automatic recovery from a single component failure. Automatic traffic recovery within 1 second for a single-link failure, with no host reboot and a clearly recorded event. Perform controlled cable, port, and switch-path failure tests while monitoring application behavior and recovery time. Fault recovery limits training interruptions and protects long-running jobs from avoidable infrastructure failures. 5%
Telemetry and Operations Monitoring should expose link utilization, error counters, retransmission or recovery events, congestion indicators, temperature, and power status. Real-time dashboards plus historical exports with node, adapter, port, and switch-level correlation. Inspect the management interface, alert rules, API availability, log retention, and integration with existing monitoring systems. Detailed telemetry shortens troubleshooting time and helps identify whether performance problems originate in hardware, topology, or software. 4%
Interoperability and Lifecycle Support The manufacturer should provide a tested compatibility matrix for server firmware, network adapters, switch firmware, operating systems, drivers, and training software. Documented version support for the complete stack, with security updates and firmware maintenance available for at least three years. Request compatibility documents, release schedules, upgrade procedures, service-level commitments, and rollback guidance. Uncontrolled version changes can cause performance regressions or make a multi-node cluster difficult to maintain. 4%
Recommended use: score each dimension from 1 to 5, multiply by the suggested weight, and require the manufacturer to provide repeatable test results for the exact server, adapter, switch, firmware, and software configuration being quoted.

Calculate Three-Year TCO from PUE, Energy Costs, and Utilization Rates

How to Choose a Cloud AI Server Manufacturer?

A credible manufacturer should provide measured PUE data, not only attractive estimates. PUE shows total facility energy divided by IT equipment energy. A lower value usually means better cooling and power efficiency. However, test conditions matter. Ask for the measurement period, ambient temperature, rack density, and workload used.

Estimate three-year electricity costs with this formula: IT load × utilization × 8,760 hours × PUE × electricity price × three years. For example, a 100-kilowatt cluster running at 60% utilization, with a 1.35 PUE and a $0.30 tariff, costs about $638,600 over three years. This excludes hardware, support, networking, space, and backup power. Use local energy rates, because a small tariff change can reshape the budget.

Utilization deserves careful review. A server rated for 100 kilowatts may run at 25% during quiet hours and reach 90% during model training. Hourly telemetry is more reliable than a single average. My early estimates were too optimistic because they ignored idle periods and cooling spikes. That mistake affected capacity planning.

Request power curves, thermal records, service response times, and replacement policies before comparing suppliers. A strong manufacturer should explain unclear figures and support independent verification. Cheap hardware can become expensive when utilization stays low. Forecast real workloads, not ideal ones.

Verify ISO/IEC 27001 Security, Warranty Coverage, and SLA Performance

Choosing a cloud AI server manufacturer requires more than comparing GPU counts or purchase prices.

ISO/IEC 27001 certification should be verified through a current certificate, accreditation details, and a matching scope statement. The scope must cover engineering, production, support, and cloud operations—not only an administrative office. Ask for the latest surveillance-audit status and corrective-action records. A certificate alone is not proof.

Security evidence should connect with real operating controls. Verizon’s 2024 Data Breach Investigations Report analyzed 30,458 incidents, including 10,626 confirmed breaches. Third-party involvement reached 15%, showing why supplier access and subcontractor controls matter. Request privileged-access logs, vulnerability response times, backup testing results, and employee security-training records. These details expose gaps that polished sales documents may hide.

Warranty terms deserve equal scrutiny. Confirm replacement-part availability, on-site response windows, firmware support, and exclusions for thermal damage or unauthorized modifications. The SLA should define measurable uptime, inference latency, maintenance notice, incident escalation, and service-credit rules. IBM’s Cost of a Data Breach Report 2024 placed the global average breach cost at 4.88 million dollars, a record high. Downtime and weak recovery plans can therefore outweigh a lower server quote. Ask for twelve months of anonymized SLA data, including missed targets and mean time to resolution. Some suppliers may provide impressive averages while omitting difficult incidents. That omission matters.

FAQS

Why should workload definition come before choosing an AI server manufacturer?

Training, inference, and recommendation workloads stress hardware differently. Define models, users, response limits, and expected data volumes first.

How should training performance be compared?

Use standardized training benchmarks that measure time to reach target model quality. Compare workloads resembling language, vision, recommendation, or speech tasks.

What should inference testing include?

Measure latency, throughput, concurrent users, power use, and cost per request. Test online requests, offline batches, and interactive streams.

Can high throughput guarantee fast real-time responses?

No. Large batches may improve throughput while increasing individual response time. A busy screen can expose that weakness quickly.

What networking details should be checked for multi-node systems?

Request measured throughput using collective workloads, not isolated port tests. Check 400-Gb/s links, adapter support, cables, latency, RDMA, and error counters.

How can multi-node scaling problems be revealed?

Run all-reduce and all-to-all tests across two, eight, and sixteen nodes. Record efficiency, tail latency, power use, and link recovery.

How should three-year electricity costs be estimated?

Use this formula: IT load × utilization × 8,760 hours × PUE × electricity price × three years. For example, a 100-kilowatt cluster at 60% utilization, 1.35 PUE, and $0.30 costs about $638,600.

What should be checked when evaluating PUE and utilization?

Ask for measurement periods, temperatures, rack density, workload details, and hourly power records. One attractive average can hide expensive cooling spikes.

What support evidence should a manufacturer provide?

Request firmware records, burn-in reports, spare-part policies, replacement procedures, test scripts, and response-time commitments. Keep records.

Why is a short pilot valuable before purchasing?

Your models and datasets may expose bottlenecks that polished specifications hide. My own estimates were imperfect, especially during idle periods.

Conclusion

Choosing the right cloud ai server manufacturer requires a structured evaluation of performance, scalability, cost, and reliability. Start by defining your workloads with MLPerf Training and Inference benchmarks to understand whether your applications prioritize model development, real-time responses, or large-scale batch processing. Compare GPU configurations by examining memory capacity and bandwidth, such as 80-GB HBM3 and 3.35-TB/s throughput, while also considering software compatibility and future upgrade options.

Networking is equally important for distributed AI, so evaluate 400-Gb/s InfiniBand connectivity, latency, and multi-node scaling efficiency. A complete decision should include a three-year total cost of ownership analysis covering PUE, energy prices, maintenance, and actual utilization rates. Finally, verify ISO/IEC 27001 security practices, warranty terms, technical support, and SLA performance history. The best provider should deliver consistent computing capacity, transparent operating costs, strong data protection, and dependable service for changing AI workloads.
Sophia

Sophia

Sophia is a dedicated marketing professional with an exceptional depth of knowledge about her company's products and services. With a keen understanding of market trends and customer needs, she crafts insightful blog posts that not only inform but also engage readers, enriching the company’s online......